Notes
blogs
Short essays on document AI, ancient scripts, and how research gets done.
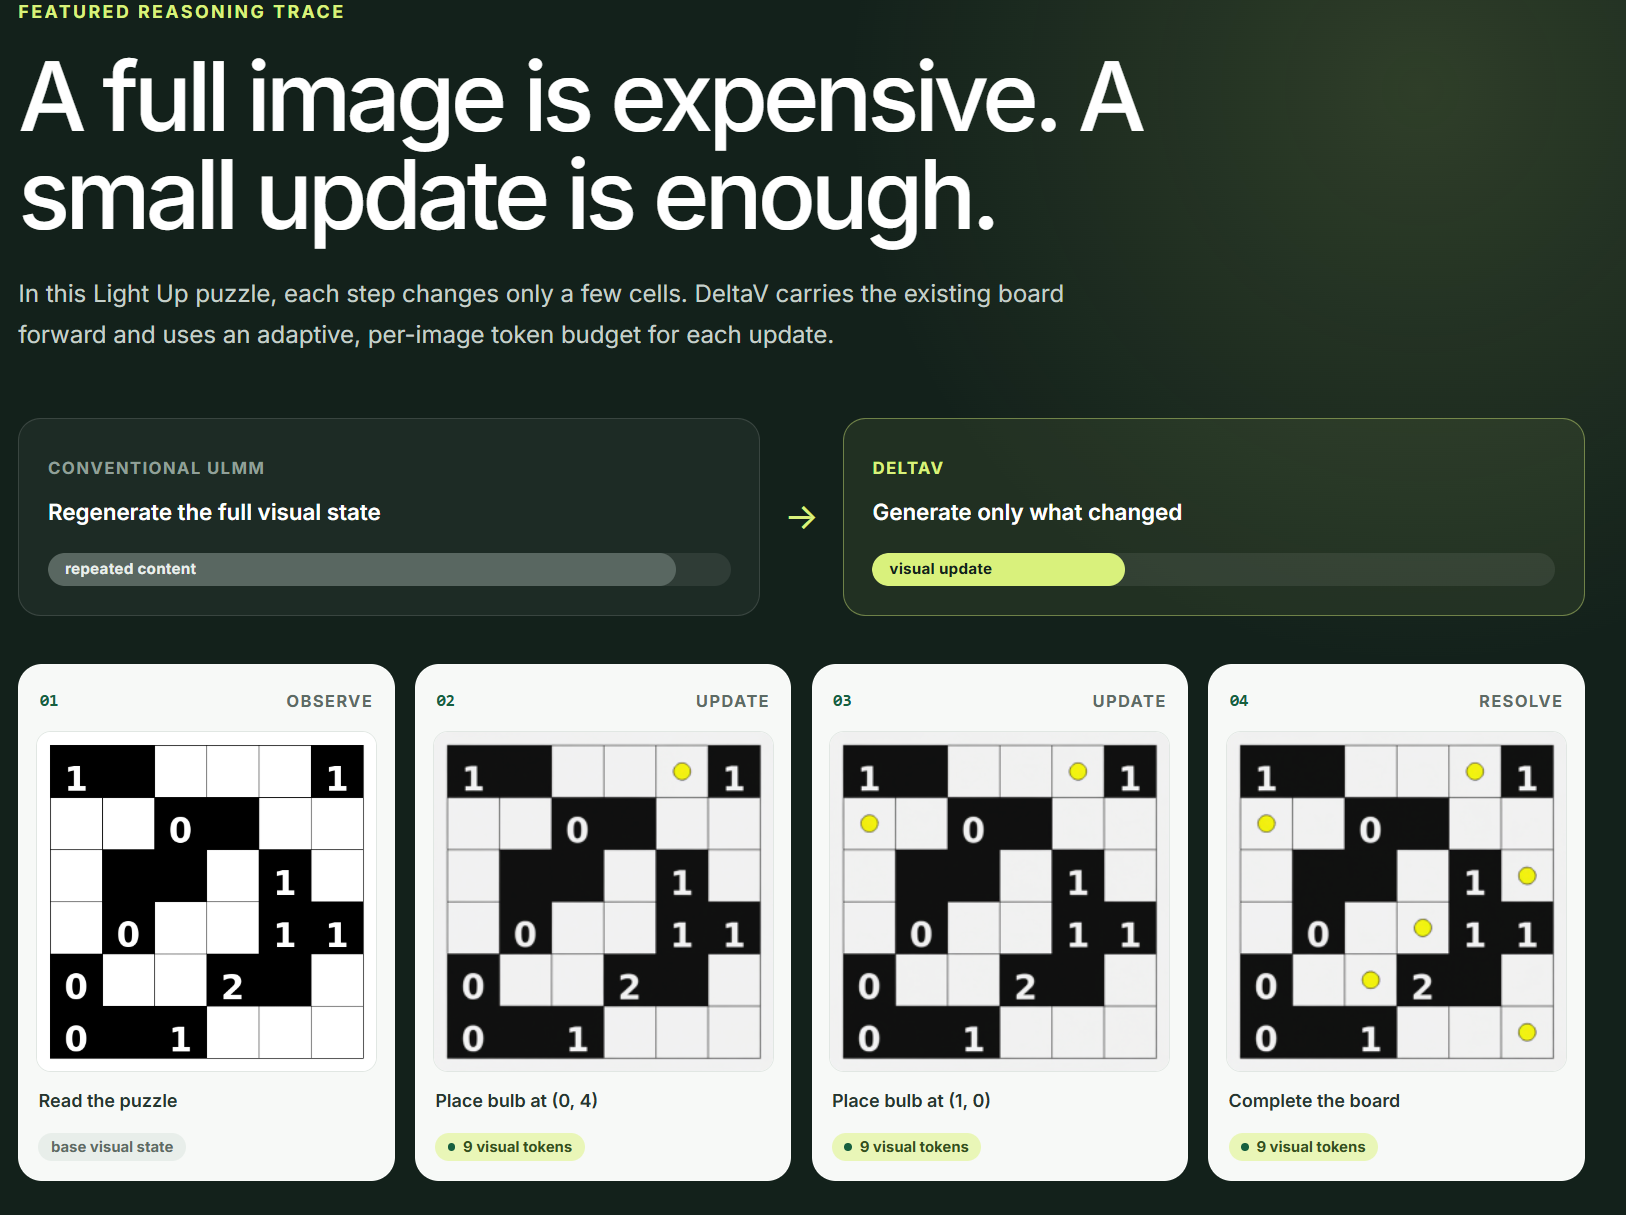
DeltaV: Thinking with Visual State Updates in Unified Large Multimodal Models
A unified multimodal large model reasons by explicitly and progressively updating its own visual state, interleaving textual thinking with iterative image editing rather than generating an image in a single pass. This approach substantially reduces token usage while improving visual reasoning performance.
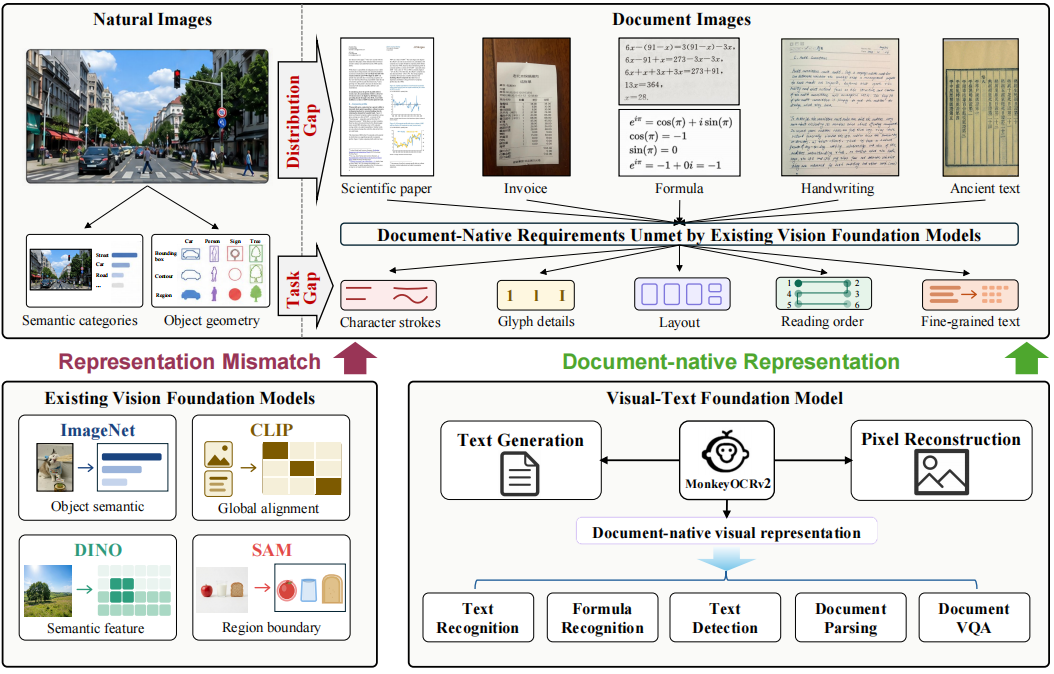
MonkeyOCRv2: A Visual-Text Foundation Model for Document AI
Most document-AI systems still run on vision encoders — CLIP, SigLIP, SAM, DINO — trained on natural images that never learned to see a stroke, a decimal point, or a reading order. MonkeyOCRv2 is our attempt at the visual encoder documents actually deserve: pretrained on MonkeyDoc v2 (113M images, 17 languages) by jointly learning image-to-text generation and pixel-level reconstruction. Frozen and paired with a 0.6B language model, its 0.1B encoder sets a new open-source state of the art on multilingual document parsing — matching or beating models an order of magnitude larger.

OCR in the LLM era
A github repo collecting recent papers.
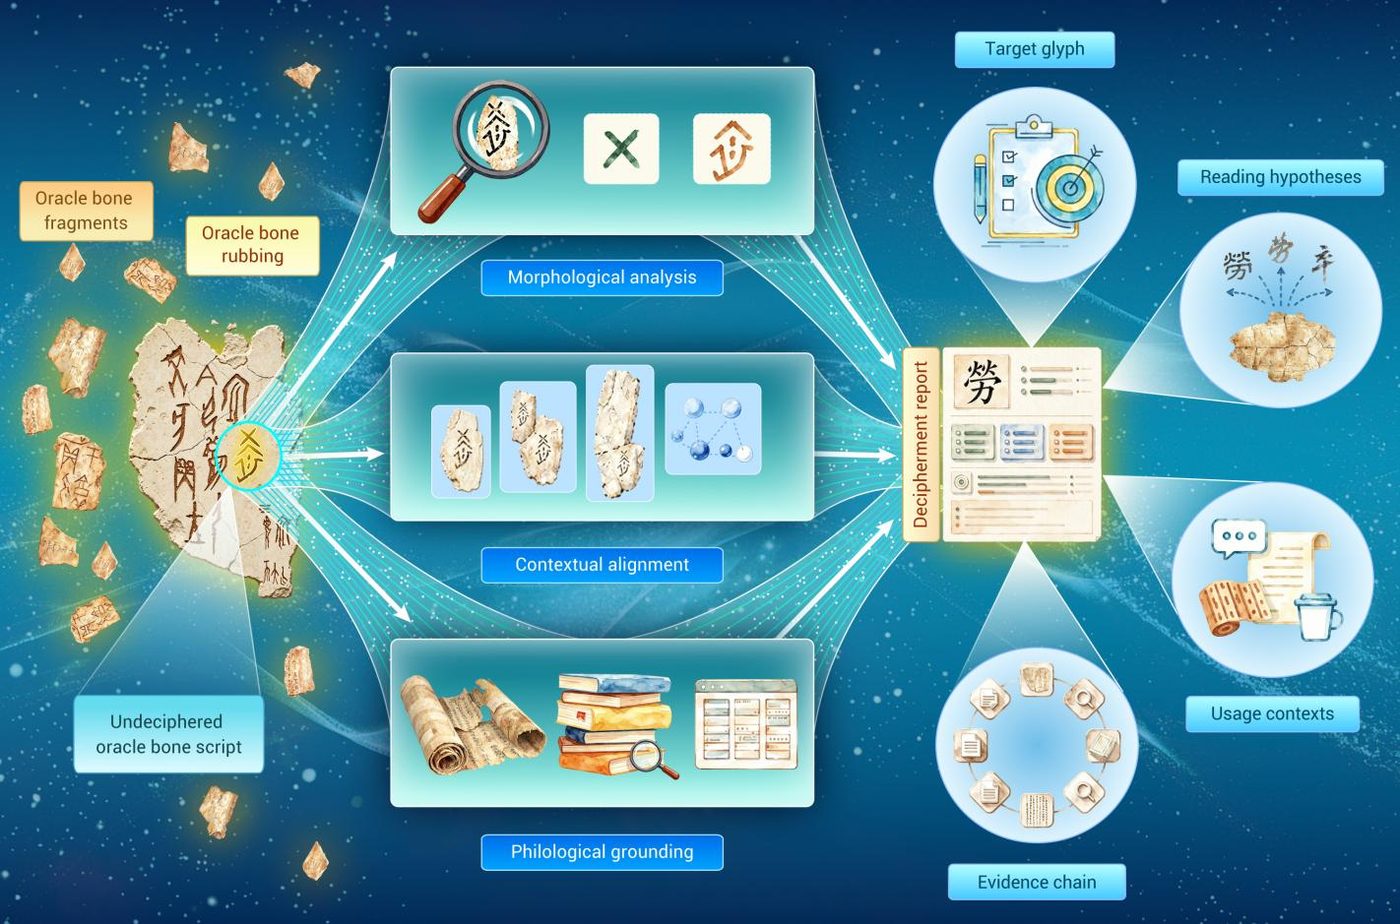
AlphaOracle: Deciphering Oracle-Bone Script
An AI system that deciphers oracle-bone script the way a paleographer does — morphology, context, and philology, fused into a verifiable evidence chain.